RAG expliqué pour débutants — guide simple
RAG expliqué simplement : la génération augmentée par récupération permet à l'IA de répondre avec vos docs. Pipeline, cas d'usage et pièges débutants.
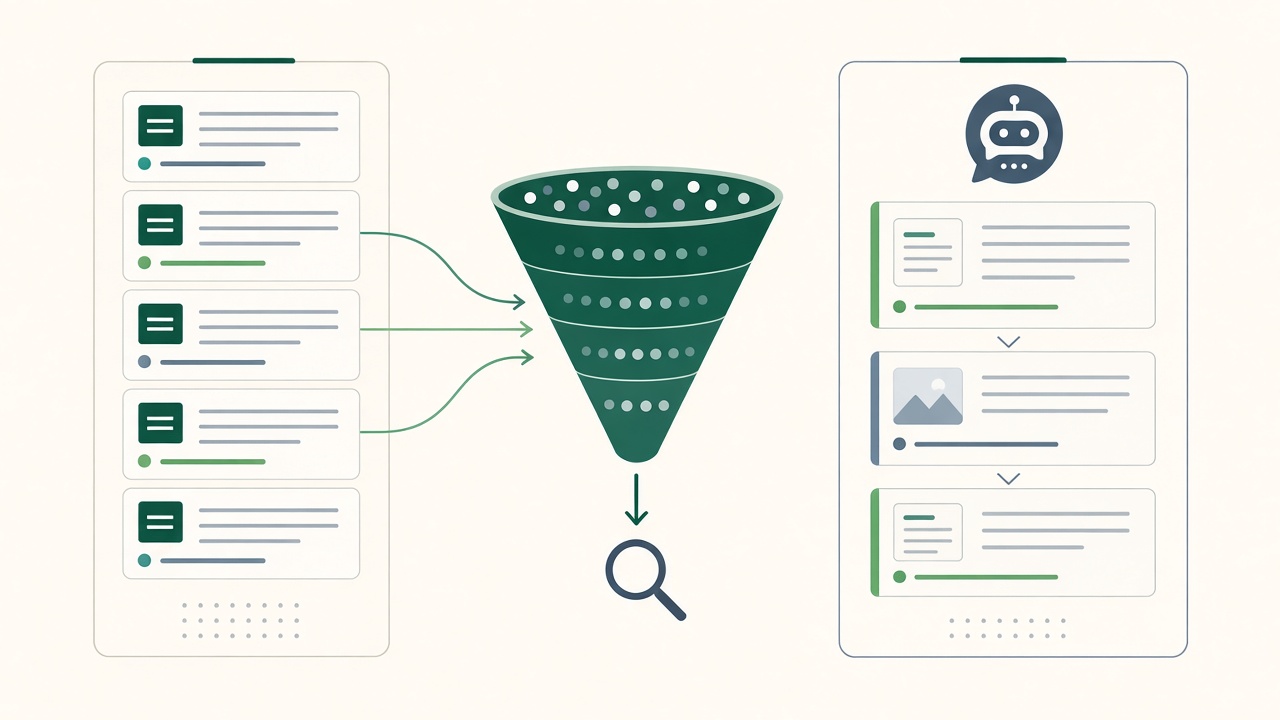
Qu'est-ce que le RAG ?
Support kept answering the same policy questions with slightly wrong details — the model “remembered” old blog posts that contradicted the official handbook. RAG explained in practice meant searching the handbook first, then answering only from those snippets. Accuracy jumped without retraining anything.
Le RAG (retrieval-augmented generation) : chercher d'abord dans vos documents, puis demander au modèle de répondre avec ces extraits. Réduit les hallucinations sur connaissances d'entreprise.
Why RAG expliqué débutant Matters
RAG est un mot-clé IA mid-funnel. Des explainers clairs renforcent la profondeur du cluster IA.
The Story Behind RAG expliqué débutant
The problem RAG solves
Large language models improvise when they lack grounded context. For company policies, product docs, and internal wikis, improvisation looks like confident wrong answers. Retrieval-augmented generation fixes the grounding step: find relevant passages, then generate an answer constrained by those passages.
RAG is not magic search. It is a pipeline: chunk documents, retrieve top matches for a question, inject them into the prompt, and instruct the model to cite or refuse when evidence is missing.
Beginners hear “vector database” and overbuild. Often keyword search plus good chunking plus strict prompting teaches the pattern faster than infrastructure cosplay.
Pipeline pieces in plain English
Chunk documents into passages small enough to fit context windows but large enough to preserve meaning — often a few paragraphs, not whole PDFs.
Retrieve with embeddings and vector search or with keyword search for structured FAQs. Top-k passages (often three to five) feed the prompt.
Prompt the model: answer only from provided sections; quote or cite chunk IDs; say “not found” if evidence is insufficient. That instruction is half the battle.
- Chunk → index → retrieve top-k
- Prompt with passages + citation rules
- Evaluate with real user questions
- Iterate chunk size and retrieval before scaling infra
Hands-on learning without overengineering
Collect ten FAQs your team actually asks. Split source docs into sections manually if needed. For each question, pick the three best sections by hand first — you are learning relevance intuition.
Automate retrieval next with simple search. Compare automated picks to your manual picks. Where they diverge, fix chunk boundaries or headings.
Measure accuracy on the ten-question set before adding agents, fancy rerankers, or multi-hop reasoning. RAG quality gates everything downstream.
RAG versus bigger prompts and versus fine-tuning
If all knowledge fits in one context window and changes rarely, a big prompt may suffice. RAG wins when knowledge is large, updates often, or must be auditable via citations.
Fine-tuning changes model weights and is costly to refresh. RAG keeps the model fixed and updates docs independently — better for policies and product catalogs that change weekly.
After this guide, deepen prompt engineering and automation on Sturdee — RAG is retrieval discipline plus prompts, not a separate religion.
Pipeline RAG en langage clair
- Découper documents en passages
- Embedding ou recherche mots-clés
- Injecter top chunks dans le prompt
- Exiger citations vers IDs de chunks
- Évaluer avec jeux de questions réels
RAG vs prompt plus long
- Collecter 10 FAQ cibles
- Découper docs en petites sections
- Récupérer top 3 sections par question
- Prompt : répondre seulement depuis sections ; dire si absent
- Mesurer précision avant infra fancy
Erreurs RAG courantes
- Chunks trop grands ou trop petits
- Pas d'obligation de citation
- Confiance retrieval sans tests requêtes
- Agents avant qualité RAG
Apprendre l'IA appliquée ensuite
Après ce guide, étudiez prompt engineering et automatisation IA — RAG = prompts + discipline de retrieval.
Takeaways — What to Do Next
RAG explained for beginners is retrieve-then-generate with citations: chunk docs, fetch top passages, constrain answers, evaluate on real questions. Master that loop before vector databases become a hobby.
RAG — FAQ
Frequently Asked Questions
RAG = fine-tuning ?+
Non. Fine-tuning change les poids. RAG garde le modèle fixe et nourrit docs à la question.
Vector DB obligatoire pour apprendre RAG ?+
Pas au début. Recherche mots-clés suffit pour l'habitude retrieve-then-generate.
Continuer à apprendre en interactif
/learn/ai →